What is Keyword Research in SEO: 2026 Intent Mapping Strategies
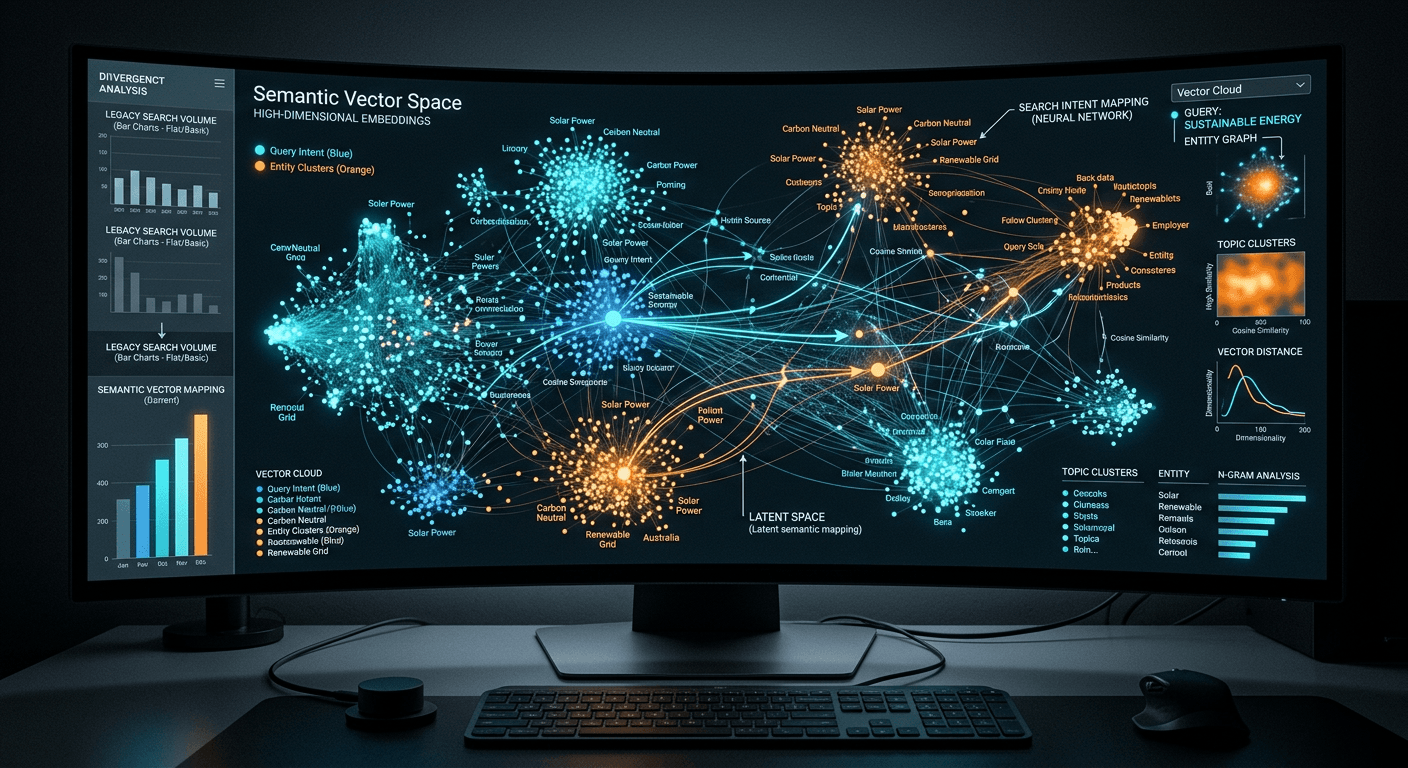
If you ask a product team dealing with generative engines what is keyword research in seo, they frequently point to legacy dashboards detailing monthly search volumes, cost-per-click averages, and historical click-through rates. This assumes search engines and language models still parse text as isolated strings of characters, waiting for an exact textual match to trigger a ranking. They do not. Modern search algorithms rely on vector embeddings and entity relationships to construct answers, meaning queries are no longer matched word-for-word, but concept-for-concept. Optimizing for isolated phrases without connecting them to a broader knowledge graph leaves content invisible to the AI agents and conversational search interfaces driving modern traffic. Understanding how keyword research operates right now requires abandoning exact-match density in favor of mapping complete entity clusters and targeting the underlying intent that forces algorithms to retrieve your data.
Quick Summary
Keyword research in modern SEO is the process of mapping semantic relationships, user intents, and entity associations to dictate how search engines and large language models retrieve your content. It prioritizes topical coverage and contextual relevance over raw search volume.
- Entity retrieval has entirely replaced exact-match keyword indexing.
- Search intent dictates the required content format, dividing queries into definitional, procedural, comparative, and diagnostic categories.
- Keyword clustering relies on search engine result page (SERP) overlap rather than linguistic similarity.
- Evaluating difficulty now demands assessing a domain's topical authority rather than merely counting inbound links.
- Modern tooling analyzes vector proximity to group relevant concepts logically.
Table of Contents
- The shift from search volume to entity retrieval
- Mapping intent over surface-level queries
- Structuring topics with seo keyword clustering
- Evaluating tools to capture search patterns
- Where teams break seo keyword best practices
- FAQ
- Recommended Reads
The shift from search volume to entity retrieval
Search volume historically dictated the value of a target phrase. A query generating ten thousand monthly searches received priority over a query generating fifty. This math breaks down entirely when language models and semantic search engines synthesize answers instead of serving lists of blue links.
Modern search relies on vector embeddings, converting words and phrases into high-dimensional numerical representations. A natural language processing model evaluates these arrays to determine proximity between concepts. When a user queries a technical problem, the engine does not search its index for those specific words; it searches its vector space for the most complete, authoritative cluster of related entities.
Why traditional metrics fail AI engines
Relying on legacy volume metrics creates a dangerous blind spot. Traffic that previously landed on a website via informational queries is now frequently absorbed directly by the search interface itself through AI overviews or generative snippets. A query with massive historical volume might yield zero outbound clicks today because the engine answers the query natively.
Furthermore, generative engines cluster synonymous queries dynamically. Fifty distinct long-tail variations of a question might show zero search volume in a traditional database because clickstream providers cannot capture AI chat interactions. However, combined, those fifty variations represent a highly active entity cluster. Prioritizing only high-volume, exact-match strings results in shallow content that fails to provide the depth required for an AI citation.
Mapping intent over surface-level queries
Capturing search visibility requires reverse-engineering the reason a user typed a query in the first place. Intent mapping categorizes keywords by the specific outcome the user expects. When the content format fails to match the algorithmic expectation for a query, the page will not rank, regardless of the domain's strength or the content's length.
Search intent fractures into four distinct operational categories:
- Definitional intent: The user requires a factual answer or explanation. The engine expects concise, structured data, often extracted into a summary card. Long, narrative introductions fail here.
- Procedural intent: The user needs to accomplish a task. The engine prioritizes numbered lists, step-by-step formatting, and code snippets or configuration examples.
- Comparative intent: The user is evaluating options. The engine rewards objective comparisons, feature matrices, and structured tables rather than biased sales copy.
- Diagnostic intent: The user is troubleshooting a specific failure mode. The engine looks for symptom descriptions, root cause analysis, and actionable resolutions.
Diagnosing seo keyword difficulty in 2026
Historically, difficulty metrics merely quantified the backlink profiles of the pages ranking on page one. If the top ten results possessed thousands of referring domains, the keyword was deemed too difficult for a new site. Today, diagnosing seo keyword difficulty requires evaluating topical density.
A domain with immense link authority but only one page about a specific software architecture will frequently be outranked by a much smaller domain that houses fifty interconnected, highly specific articles on that exact architecture. Search algorithms assess risk; they prefer citing a specialized source that comprehensively covers an entity over a generalist site lacking topical depth. Difficulty is now a measure of how thoroughly the competitors have mapped the entity graph, not just how many links they have accumulated.
| Assessment Vector | Legacy Difficulty Analysis | Modern Semantic Difficulty Analysis |
|---|---|---|
| Primary Metric | Inbound referring domains to the URL | Topical coverage and entity density across the domain |
| Competitor Check | Domain Rating / Domain Authority | Knowledge graph presence and internal linking structures |
| Content Requirement | High word count and exact keyword density | Completeness of sub-topics and factual accuracy |
| Success Indicator | Out-linking the top competitors | Answering the query faster and more accurately than competitors |
Structuring topics with seo keyword clustering
Attempting to write a unique page for every individual search phrase causes keyword cannibalization, where a single domain forces its own pages to compete against one another for the same vector space. To prevent this, practitioners use seo keyword clustering to group distinct queries that require the same answer into a single targetable topic.
The mechanics of semantic grouping
Effective grouping is not based on linguistic similarity, but on algorithmic behavior. Two keywords might look completely different textually but share the exact same intent. Conversely, two keywords might share almost all of their characters but require entirely different pages.
Practical rule: Group keywords by SERP overlap rather than semantic similarity. If three distinct queries trigger the same four competitors on page one, the algorithm views them as the same topic, and they belong in the same cluster.
Agglomerative clustering tools automate this by scraping the search results for hundreds of target queries and grouping them based on a predefined overlap threshold. A standard operational threshold is three shared URLs. If Query A and Query B return at least three identical pages in their top ten results, they are clustered together and mapped to a single piece of content. This reduces content bloat, consolidates link equity, and ensures the resulting page possesses the comprehensiveness generative algorithms require to construct a citation.
Evaluating tools to capture search patterns
The infrastructure required to analyze entities, track AI citations, and cluster topics via SERP overlap is fundamentally different from the software used a decade ago. Legacy volume aggregators rely on purchased clickstream data, which is heavily biased toward traditional browser-based searches and entirely blind to queries processed through enterprise AI agents or private LLM interfaces.
What a modern seo keyword finder actually does
When a team evaluates a modern seo keyword finder, they must look past the standard monthly volume metrics. Modern platforms operate by reverse-engineering the entity graphs built by search engines. Instead of outputting a linear list of phrases, a contemporary tool provides a topical map.
These tools process seed terms through natural language APIs to extract related entities, identifying the exact subtopics, questions, and formatting structures currently rewarded by the algorithm. They analyze "People Also Ask" arrays and semantic variants at scale to reveal the hidden questions users ask immediately after their initial query. Operating this way requires AI-driven SEO for AI companies that aligns directly with how modern algorithms digest content. A platform capable of reading vector relationships ensures that the content strategy targets the whole concept rather than just isolated fragments.
Where teams break seo keyword best practices
Even with an accurate understanding of intent and entity clustering, operational execution frequently fails when teams apply legacy production habits to modern architectural requirements. Breaking seo keyword best practices usually occurs at the organizational level, manifesting in several predictable failure modes.
Chasing broad terms without topical authority
The most common failure is the "head term" trap. A startup launching a new data pipeline tool immediately attempts to rank for "data integration." Because they lack an established entity footprint for that topic, the engine views their single piece of content as high-risk and ignores it. The correct approach is to build a foundation of highly specific, low-competition diagnostic queries (e.g., "how to resolve schema drift in PostgreSQL to Snowflake pipelines"). Securing visibility on the narrow technical edges builds the topical authority required to eventually compete for the broader terms.
Another frequent organizational failure is separating keyword research from technical format. A team will identify a highly relevant cluster, assign it to a writer, and receive a narrative essay. If the primary queries in that cluster demand procedural intent, the narrative essay will fail to rank. The research process must dictate the exact HTML structure - lists, tables, code blocks, or schema markup - required to satisfy the algorithmic parsing of that topic.
Finally, teams fail by treating research as a static, one-time event. Language models continuously update their weights based on new data and shifting user behaviors. A cluster that was informational six months ago might shift toward comparative intent today as new products enter the market. Keyword research in 2026 is an ongoing diagnostic process of monitoring SERP volatility and adjusting content structures the moment the underlying algorithmic intent shifts.
FAQ
What is the difference between keyword difficulty and topical authority? Keyword difficulty historically measured the strength of the backlink profiles of competing pages. Topical authority measures the breadth and depth of a domain's content across an entire entity graph. Search engines now prioritize topical authority, frequently ranking highly relevant, specialized sites over massive domains with stronger link profiles but superficial content.
Should startups target zero-volume search terms? Yes. Zero-volume keywords in legacy tools often represent highly specific, long-tail queries or emerging technical issues that clickstream data has not yet captured. Targeting these hyper-specific terms builds initial topical authority and captures highly qualified, intent-driven traffic that competitors ignore.
How often should keyword clusters be updated? Keyword clusters should be reviewed whenever the intent of the search results changes. If you track a cluster and notice that the search engine is suddenly rewarding comparison tables instead of procedural guides, the cluster's intent has shifted, and the mapped content must be restructured immediately.
Does exact-match keyword density matter for AI citations? No. Large language models and semantic search engines use vector embeddings to understand concepts, not text-matching algorithms to count words. Forcing exact-match phrases into content degrades readability without providing any algorithmic benefit. Focus on comprehensive entity coverage rather than specific word counts.